

[Sep-2026] Use Real Databricks-Machine-Learning-Associate Dumps Free Sample Questions and Practice Test Engine
Pass Databricks Databricks-Machine-Learning-Associate exam - questions - convert Tets Engine to PDF
Databricks Databricks-Machine-Learning-Associate Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 41
A data scientist is performing hyperparameter tuning using an iterative optimization algorithm. Each evaluation of unique hyperparameter values is being trained on a single compute node. They are performing eight total evaluations across eight total compute nodes. While the accuracy of the model does vary over the eight evaluations, they notice there is no trend of improvement in the accuracy. The data scientist believes this is due to the parallelization of the tuning process.
Which change could the data scientist make to improve their model accuracy over the course of their tuning process?
- A. Change the number of compute nodes and the number of evaluations to be much larger but equal.
- B. Change the iterative optimization algorithm used to facilitate the tuning process.
- C. Change the number of compute nodes to be double or more than double the number of evaluations.
- D. Change the number of compute nodes to be half or less than half of the number of evaluations.
Answer: B
Explanation:
The lack of improvement in model accuracy across evaluations suggests that the optimization algorithm might not be effectively exploring the hyperparameter space. Iterative optimization algorithms like Tree-structured Parzen Estimators (TPE) or Bayesian Optimization can adapt based on previous evaluations, guiding the search towards more promising regions of the hyperparameter space.
Changing the optimization algorithm can lead to better utilization of the information gathered during each evaluation, potentially improving the overall accuracy.
Reference:
Hyperparameter Optimization with Hyperopt
NEW QUESTION # 42
A data scientist is using MLflow to track their machine learning experiment. As a part of each of their MLflow runs, they are performing hyperparameter tuning. The data scientist would like to have one parent run for the tuning process with a child run for each unique combination of hyperparameter values. All parent and child runs are being manually started with mlflow.start_run.
Which of the following approaches can the data scientist use to accomplish this MLflow run organization?
- A. They can specify nested=True when starting the child run for each unique combination of hyperparameter values
- B. They can start each child run inside the parent run's indented code block using mlflow.start runO
- C. They can start each child run with the same experiment ID as the parent run
- D. They can turn on Databricks Autologging
- E. They can specify nested=True when starting the parent run for the tuning process
Answer: A
Explanation:
To organize MLflow runs with one parent run for the tuning process and a child run for each unique combination of hyperparameter values, the data scientist can specify nested=True when starting the child run. This approach ensures that each child run is properly nested under the parent run, maintaining a clear hierarchical structure for the experiment. This nesting helps in tracking and comparing different hyperparameter combinations within the same tuning process.
Reference:
MLflow Documentation (Managing Nested Runs).
NEW QUESTION # 43
Which of the following is a benefit of using vectorized pandas UDFs instead of standard PySpark UDFs?
- A. The vectorized pandas UDFs work on distributed DataFrames
- B. The vectorized pandas UDFs allow for pandas API use inside of the function
- C. The vectorized pandas UDFs process data in batches rather than one row at a time
- D. The vectorized pandas UDFs allow for the use of type hints
- E. The vectorized pandas UDFs process data in memory rather than spilling to disk
Answer: C
Explanation:
Vectorized pandas UDFs, also known as Pandas UDFs, are a powerful feature in PySpark that allows for more efficient operations than standard UDFs. They operate by processing data in batches, utilizing vectorized operations that leverage pandas to perform operations on whole batches of data at once. This approach is much more efficient than processing data row by row as is typical with standard PySpark UDFs, which can significantly speed up the computation.
Reference
PySpark Documentation on UDFs: https://spark.apache.org/docs/latest/api/python/user_guide/sql/arrow_pandas.html#pandas-udfs-a-k-a-vectorized-udfs
NEW QUESTION # 44
An organization is developing a feature repository and is electing to one-hot encode all categorical feature variables. A data scientist suggests that the categorical feature variables should not be one-hot encoded within the feature repository.
Which of the following explanations justifies this suggestion?
- A. One-hot encoding is a potentially problematic categorical variable strategy for some machine learning algorithms.
- B. One-hot encoding is computationally intensive and should only be performed on small samples of training sets for individual machine learning problems.
- C. One-hot encoding is not a common strategy for representing categorical feature variables numerically.
- D. One-hot encoding is not supported by most machine learning libraries.
- E. One-hot encoding is dependent on the target variable's values which differ for each application.
Answer: A
Explanation:
One-hot encoding transforms categorical variables into a format that can be provided to machine learning algorithms to better predict the output. However, when done prematurely or universally within a feature repository, it can be problematic:
Dimensionality Increase: One-hot encoding significantly increases the feature space, especially with high cardinality features, which can lead to high memory consumption and slower computation.
Model Specificity: Some models handle categorical variables natively (like decision trees and boosting algorithms), and premature one-hot encoding can lead to inefficiency and loss of information (e.g., ordinal relationships).
Sparse Matrix Issue: It often results in a sparse matrix where most values are zero, which can be inefficient in both storage and computation for some algorithms.
Generalization vs. Specificity: Encoding should ideally be tailored to specific models and use cases rather than applied generally in a feature repository.
Reference
"Feature Engineering and Selection: A Practical Approach for Predictive Models" by Max Kuhn and Kjell Johnson (CRC Press, 2019).
NEW QUESTION # 45
A data scientist has developed a machine learning pipeline with a static input data set using Spark ML, but the pipeline is taking too long to process. They increase the number of workers in the cluster to get the pipeline to run more efficiently. They notice that the number of rows in the training set after reconfiguring the cluster is different from the number of rows in the training set prior to reconfiguring the cluster.
Which of the following approaches will guarantee a reproducible training and test set for each model?
- A. Manually configure the cluster
- B. Set a speed in the data splitting operation
- C. Write out the split data sets to persistent storage
- D. Manually partition the input data
Answer: C
Explanation:
To ensure reproducible training and test sets, writing the split data sets to persistent storage is a reliable approach. This allows you to consistently load the same training and test data for each model run, regardless of cluster reconfiguration or other changes in the environment.
Correct approach:
Split the data.
Write the split data to persistent storage (e.g., HDFS, S3).
Load the data from storage for each model training session.
train_df, test_df = spark_df.randomSplit([0.8, 0.2], seed=42) train_df.write.parquet("path/to/train_df.parquet") test_df.write.parquet("path/to/test_df.parquet") # Later, load the data train_df = spark.read.parquet("path/to/train_df.parquet") test_df = spark.read.parquet("path/to/test_df.parquet") Reference:
Spark DataFrameWriter Documentation
NEW QUESTION # 46
A machine learning engineer is trying to scale a machine learning pipeline by distributing its single-node model tuning process. After broadcasting the entire training data onto each core, each core in the cluster can train one model at a time. Because the tuning process is still running slowly, the engineer wants to increase the level of parallelism from 4 cores to 8 cores to speed up the tuning process. Unfortunately, the total memory in the cluster cannot be increased.
In which of the following scenarios will increasing the level of parallelism from 4 to 8 speed up the tuning process?
- A. When the tuning process in randomized
- B. When the model is unable to be parallelized
- C. When the data is particularly wide in shape
- D. When the entire data can fit on each core
- E. When the data is particularly long in shape
Answer: D
Explanation:
Increasing the level of parallelism from 4 to 8 cores can speed up the tuning process if each core can handle the entire dataset. This ensures that each core can independently work on training a model without running into memory constraints. If the entire dataset fits into the memory of each core, adding more cores will allow more models to be trained in parallel, thus speeding up the process.
Reference:
Parallel Computing Concepts
NEW QUESTION # 47
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function and they have defined the search space search_space.
As a result, they have the following code block: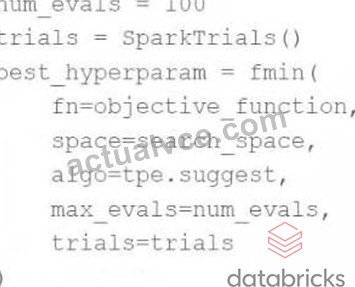
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Remove the trials=trials argument
- B. Change fmin() to fmax()
- C. Reduce num_evals to be less than 10
- D. Change SparkTrials() to Trials()
- E. Remove the algo=tpe.suggest argument
Answer: D
Explanation:
The SparkTrials() is used to distribute trials of hyperparameter tuning across a Spark cluster. If the environment does not support Spark or if the user prefers not to use distributed computing for this purpose, switching to Trials() would be appropriate. Trials() is the standard class for managing search trials in Hyperopt but does not distribute the computation. If the user is encountering issues with SparkTrials() possibly due to an unsupported configuration or an error in the cluster setup, using Trials() can be a suitable change for running the optimization locally or in a non-distributed manner.
Reference
Hyperopt documentation: http://hyperopt.github.io/hyperopt/
NEW QUESTION # 48
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Iterative optimization
- B. Spark ML cannot distribute linear regression training
- C. Singular value decomposition
- D. Least-squares method
- E. Logistic regression
Answer: A
Explanation:
For large datasets with many variables, Spark ML distributes the training of a linear regression model using iterative optimization methods. Specifically, Spark ML employs algorithms such as Gradient Descent or L-BFGS (Limited-memory Broyden-Fletcher-Goldfarb-Shanno) to iteratively minimize the loss function. These iterative methods are suitable for distributed computing environments and can handle large-scale data efficiently by partitioning the data across nodes in a cluster and performing parallel updates.
Reference:
Spark MLlib Documentation (Linear Regression with Iterative Optimization).
NEW QUESTION # 49
A data scientist has been given an incomplete notebook from the data engineering team. The notebook uses a Spark DataFrame spark_df on which the data scientist needs to perform further feature engineering. Unfortunately, the data scientist has not yet learned the PySpark DataFrame API.
Which of the following blocks of code can the data scientist run to be able to use the pandas API on Spark?
- A. spark_df.to_sql()
- B. import pyspark.pandas as ps
df = ps.DataFrame(spark_df) - C. import pandas as pd
df = pd.DataFrame(spark_df) - D. import pyspark.pandas as ps
df = ps.to_pandas(spark_df) - E. spark_df.to_pandas()
Answer: B
Explanation:
To use the pandas API on Spark, which is designed to bridge the gap between the simplicity of pandas and the scalability of Spark, the correct approach involves importing the pyspark.pandas (recently renamed to pandas_api_on_spark) module and converting a Spark DataFrame to a pandas-on-Spark DataFrame using this API. The provided syntax correctly initializes a pandas-on-Spark DataFrame, allowing the data scientist to work with the familiar pandas-like API on large datasets managed by Spark.
Reference
Pandas API on Spark Documentation: https://spark.apache.org/docs/latest/api/python/user_guide/pandas_on_spark/index.html
NEW QUESTION # 50
A team is developing guidelines on when to use various evaluation metrics for classification problems. The team needs to provide input on when to use the F1 score over accuracy.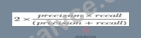
Which of the following suggestions should the team include in their guidelines?
- A. The F1 score should be utilized over accuracy when there is significant imbalance between positive and negative classes and avoiding false negatives is a priority.
- B. The F1 score should be utilized over accuracy when there are greater than two classes in the target variable.
- C. The F1 score should be utilized over accuracy when identifying true positives and true negatives are equally important to the business problem.
- D. The F1 score should be utilized over accuracy when the number of actual positive cases is identical to the number of actual negative cases.
Answer: A
Explanation:
The F1 score is the harmonic mean of precision and recall and is particularly useful in situations where there is a significant imbalance between positive and negative classes. When there is a class imbalance, accuracy can be misleading because a model can achieve high accuracy by simply predicting the majority class. The F1 score, however, provides a better measure of the test's accuracy in terms of both false positives and false negatives.
Specifically, the F1 score should be used over accuracy when:
There is a significant imbalance between positive and negative classes.
Avoiding false negatives is a priority, meaning recall (the ability to detect all positive instances) is crucial.
In this scenario, the F1 score balances both precision (the ability to avoid false positives) and recall, providing a more meaningful measure of a model's performance under these conditions.
Reference:
Databricks documentation on classification metrics: Classification Metrics
NEW QUESTION # 51
A data scientist has developed a linear regression model using Spark ML and computed the predictions in a Spark DataFrame preds_df with the following schema:
prediction DOUBLE
actual DOUBLE
Which of the following code blocks can be used to compute the root mean-squared-error of the model according to the data in preds_df and assign it to the rmse variable?
- A.

- B.
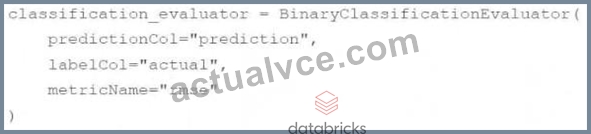
- C.
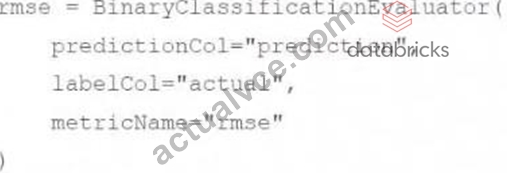
- D.
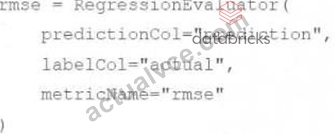
Answer: D
Explanation:
The code block to compute the root mean-squared error (RMSE) for a linear regression model in Spark ML should use the RegressionEvaluator class with metricName set to "rmse". Given the schema of preds_df with columns prediction and actual, the correct evaluator setup will specify predictionCol="prediction" and labelCol="actual". Thus, the appropriate code block (Option C in your list) that uses RegressionEvaluator to compute the RMSE is the correct choice. This setup correctly measures the performance of the regression model using the predictions and actual outcomes from the DataFrame.
Reference:
Spark ML documentation (Using RegressionEvaluator to Compute RMSE).
NEW QUESTION # 52
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Iterative optimization
- B. Singular value decomposition
- C. Least-squares method
- D. Logistic regression
Answer: A
Explanation:
For large datasets, Spark ML uses iterative optimization methods to distribute the training of a linear regression model. Specifically, Spark MLlib employs techniques like Stochastic Gradient Descent (SGD) and Limited-memory Broyden-Fletcher-Goldfarb-Shanno (L-BFGS) optimization to iteratively update the model parameters. These methods are well-suited for distributed computing environments because they can handle large-scale data efficiently by processing mini-batches of data and updating the model incrementally.
Reference:
Databricks documentation on linear regression: Linear Regression in Spark ML
NEW QUESTION # 53
A data scientist has developed a random forest regressor rfr and included it as the final stage in a Spark MLPipeline pipeline. They then set up a cross-validation process with pipeline as the estimator in the following code block: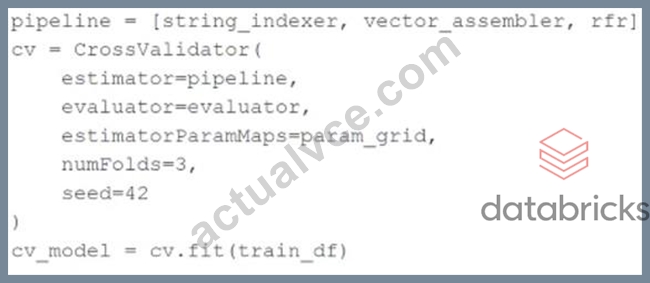
Which of the following is a negative consequence of including pipeline as the estimator in the cross-validation process rather than rfr as the estimator?
- A. The process will leak data from the training set to the test set during the evaluation phase
- B. The process will have a longer runtime because all stages of pipeline need to be refit or retransformed with each mode
- C. The process will be unable to parallelize tuning due to the distributed nature of pipeline
- D. The process will leak data prep information from the validation sets to the training sets for each model
Answer: B
Explanation:
Including the entire pipeline as the estimator in the cross-validation process means that all stages of the pipeline, including data preprocessing steps like string indexing and vector assembling, will be refit or retransformed for each fold of the cross-validation. This results in a longer runtime because each fold requires re-execution of these preprocessing steps, which can be computationally expensive.
If only the random forest regressor (rfr) were included as the estimator, the preprocessing steps would be performed once, and only the model fitting would be repeated for each fold, significantly reducing the computational overhead.
Reference:
Databricks documentation on cross-validation: Cross Validation
NEW QUESTION # 54
A data scientist has created two linear regression models. The first model uses price as a label variable and the second model uses log(price) as a label variable. When evaluating the RMSE of each model by comparing the label predictions to the actual price values, the data scientist notices that the RMSE for the second model is much larger than the RMSE of the first model.
Which of the following possible explanations for this difference is invalid?
- A. The data scientist failed to take the log of the predictions in the first model prior to computing the RMSE
- B. The first model is much more accurate than the second model
- C. The RMSE is an invalid evaluation metric for regression problems
- D. The data scientist failed to exponentiate the predictions in the second model prior to computing the RMSE
- E. The second model is much more accurate than the first model
Answer: C
Explanation:
The Root Mean Squared Error (RMSE) is a standard and widely used metric for evaluating the accuracy of regression models. The statement that it is invalid is incorrect. Here's a breakdown of why the other statements are or are not valid:
Transformations and RMSE Calculation: If the model predictions were transformed (e.g., using log), they should be converted back to their original scale before calculating RMSE to ensure accuracy in the evaluation. Missteps in this conversion process can lead to misleading RMSE values.
Accuracy of Models: Without additional information, we can't definitively say which model is more accurate without considering their RMSE values properly scaled back to the original price scale.
Appropriateness of RMSE: RMSE is entirely valid for regression problems as it provides a measure of how accurately a model predicts the outcome, expressed in the same units as the dependent variable.
Reference
"Applied Predictive Modeling" by Max Kuhn and Kjell Johnson (Springer, 2013), particularly the chapters discussing model evaluation metrics.
NEW QUESTION # 55
Which of the following describes the relationship between native Spark DataFrames and pandas API on Spark DataFrames?
- A. pandas API on Spark DataFrames are more performant than Spark DataFrames
- B. pandas API on Spark DataFrames are single-node versions of Spark DataFrames with additional metadata
- C. pandas API on Spark DataFrames are made up of Spark DataFrames and additional metadata
- D. pandas API on Spark DataFrames are less mutable versions of Spark DataFrames
Answer: C
Explanation:
The pandas API on Spark DataFrames are made up of Spark DataFrames with additional metadata. The pandas API on Spark aims to provide the pandas-like experience with the scalability and distributed nature of Spark. It allows users to work with pandas functions on large datasets by leveraging Spark's underlying capabilities.
Reference:
Databricks documentation on pandas API on Spark: pandas API on Spark
NEW QUESTION # 56
The implementation of linear regression in Spark ML first attempts to solve the linear regression problem using matrix decomposition, but this method does not scale well to large datasets with a large number of variables.
Which of the following approaches does Spark ML use to distribute the training of a linear regression model for large data?
- A. Iterative optimization
- B. Spark ML cannot distribute linear regression training
- C. Singular value decomposition
- D. Least-squares method
- E. Logistic regression
Answer: A
NEW QUESTION # 57
A data scientist learned during their training to always use 5-fold cross-validation in their model development workflow. A colleague suggests that there are cases where a train-validation split could be preferred over k-fold cross-validation when k > 2.
Which of the following describes a potential benefit of using a train-validation split over k-fold cross-validation in this scenario?
- A. Bias is avoidable when using a train-validation split
- B. Fewer hyperparameter values need to be tested when using a train-validation split
- C. Fewer models need to be trained when using a train-validation split
- D. Reproducibility is achievable when using a train-validation split
- E. A holdout set is not necessary when using a train-validation split
Answer: C
Explanation:
A train-validation split is often preferred over k-fold cross-validation (with k > 2) when computational efficiency is a concern. With a train-validation split, only two models (one on the training set and one on the validation set) are trained, whereas k-fold cross-validation requires training k models (one for each fold).
This reduction in the number of models trained can save significant computational resources and time, especially when dealing with large datasets or complex models.
Reference:
Model Evaluation with Train-Test Split
NEW QUESTION # 58
A data scientist uses 3-fold cross-validation when optimizing model hyperparameters for a regression problem. The following root-mean-squared-error values are calculated on each of the validation folds:
* 10.0
* 12.0
* 17.0
Which of the following values represents the overall cross-validation root-mean-squared error?
- A. 17.0
- B. 12.0
- C. 10.0
- D. 39.0
- E. 13.0
Answer: E
Explanation:
To calculate the overall cross-validation root-mean-squared error (RMSE), you average the RMSE values obtained from each validation fold. Given the RMSE values of 10.0, 12.0, and 17.0 for the three folds, the overall cross-validation RMSE is calculated as the average of these three values:
Overall CV RMSE=10.0+12.0+17.03=39.03=13.0Overall CV RMSE=310.0+12.0+17.0=339.0=13.0 Thus, the correct answer is 13.0, which accurately represents the average RMSE across all folds.
Reference:
Cross-validation in Regression (Understanding Cross-Validation Metrics).
NEW QUESTION # 59
In which of the following situations is it preferable to impute missing feature values with their median value over the mean value?
- A. When the features are of the categorical type
- B. When the features contain no outliers
- C. When the features contain no missing no values
- D. When the features are of the boolean type
- E. When the features contain a lot of extreme outliers
Answer: E
Explanation:
Imputing missing values with the median is often preferred over the mean in scenarios where the data contains a lot of extreme outliers. The median is a more robust measure of central tendency in such cases, as it is not as heavily influenced by outliers as the mean. Using the median ensures that the imputed values are more representative of the typical data point, thus preserving the integrity of the dataset's distribution. The other options are not specifically relevant to the question of handling outliers in numerical data.
Reference:
Data Imputation Techniques (Dealing with Outliers).
NEW QUESTION # 60
A data scientist is using Spark ML to engineer features for an exploratory machine learning project.
They decide they want to standardize their features using the following code block:
Upon code review, a colleague expressed concern with the features being standardized prior to splitting the data into a training set and a test set.
Which of the following changes can the data scientist make to address the concern?
- A. Utilize the MinMaxScaler object to standardize the training data according to global minimum and maximum values
- B. Utilize the Pipeline API to standardize the training data according to the test data's summary statistics
- C. Utilize a cross-validation process rather than a train-test split process to remove the need for standardizing data
- D. Utilize the MinMaxScaler object to standardize the test data according to global minimum and maximum values
- E. Utilize the Pipeline API to standardize the test data according to the training data's summary statistics
Answer: E
Explanation:
To address the concern about standardizing features prior to splitting the data, the correct approach is to use the Pipeline API to ensure that only the training data's summary statistics are used to standardize the test data. This is achieved by fitting the StandardScaler (or any scaler) on the training data and then transforming both the training and test data using the fitted scaler. This approach prevents information leakage from the test data into the model training process and ensures that the model is evaluated fairly.
Reference:
Best Practices in Preprocessing in Spark ML (Handling Data Splits and Feature Standardization).
NEW QUESTION # 61
......
Pass Your Databricks-Machine-Learning-Associate Exam Easily - Real Databricks-Machine-Learning-Associate Practice Dump Updated Sep 11, 2026: https://www.actualvce.com/Databricks/Databricks-Machine-Learning-Associate-valid-vce-dumps.html
2026 Realistic Verified Free Databricks Databricks-Machine-Learning-Associate Exam Questions: https://drive.google.com/open?id=1J83ciieyF6tWBfxHNYM-5_XNIOJLaK1x